
peopleremover.app Remove People from Photos Free with AI | People Remover
Remove people from photos by typing who to delete — no brushing, no watermark. Your first edit is free when you sign in.
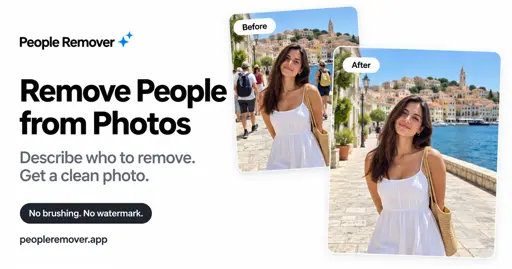
Remove people from photos by typing who to delete — no brushing, no watermark. Your first edit is free when you sign in.
Every photo retouch queue has the same bottleneck: the person who knows how to paint a precise mask is also the person who is busy. Everyone else can see the tourist in the background of the shot, and nobody else can select around him cleanly. That is not a skill problem. It is an interface problem, and it is the problem that People Remover, a describe-and-remove tool, is aimed at.
According to the product page, you upload a photo, type a sentence describing who should disappear, and download the result, with no brush and no manual selection at any point. The tool runs in a browser, including on a phone, so the person who spotted the problem is also the person who can fix it.
Brush-based editing asks a question the editor may not be able to answer precisely: which pixels belong to this person. A describe-and-remove model asks a question almost anyone can answer: who is this, and where are they standing. The difference is not cosmetic. It moves the job from the people who can select well to the people who can write one clear sentence.
The page gives the sentence patterns that work: remove the man on the left, remove the woman in the red jacket, remove everyone in the background, remove all people except the bride, remove the child sitting on the steps. Two signals repeat across those examples. Position and appearance. A description that carries both is far more likely to land on the intended person than one that carries neither.
Precision matters most when people look alike. If two people in the frame wear the same dark jacket, the sentence has to separate them, by position, by what they are doing, or by some detail that is visible in the photo.
The accepted inputs are JPG, PNG, WebP and iPhone HEIC or HEIF up to 10 MB, with HEIC converted to JPG inside the browser rather than on a server you have to wait for. Output is JPG, PNG or WebP, and the pricing section notes that paid plans can also choose 2K or 4K sizes, while the free first edit is a 1K result. No plan adds a watermark, including the free one.
Multiple people in one sentence count as a single edit. Remove everyone in the background except the bride is one edit, however many people that turns out to be. For event photography, that is the difference between a five-minute cleanup and a forty-minute one.
The page states that a failed edit returns your credits, which changes the calculation on hard photos. It is reasonable to retry with a clearer sentence rather than accept a bad output, because the attempt itself is not the cost. Access is either a one-time credit pack or a monthly plan, and the first edit is free once you sign in.
Privacy is spelled out in the FAQ. Uploaded originals and edited results are automatically deleted after one hour, and the page says photos and instructions are not used to train AI models. That hour is also a deadline: results are not stored in a profile, so the download has to happen before it expires.
The page is unusually honest about failure modes, and they are worth repeating because they define when to reach for a different tool.
Overlap is the main one. If the person being removed stands in front of, or touches, the main subject, the result can look less clean. The model has to invent what was behind them, and a hand resting on a shoulder leaves very little to invent from.
Second, the whole image is re-drawn. Small details outside the removed person can shift slightly. For a social post that is invisible; for a print order, someone has to compare the output against the original at full size.
Third, the description can be misread. The remedy is available to anyone: rewrite the sentence with one more detail and run it again.
Fourth, and most important for professional retouchers, describing is less exact than painting when you need a specific outline or a small part of a person. If the job is to remove a wrist and keep the bracelet, a brush still wins. If the job is to remove whole people from a hundred tourist photos, nobody wants to be painting.
Phone erasers are fine for a quick fix on a single photo, but controls vary by app and multi-person edits get awkward. Desktop editors give full control at the cost of skill and time. Brush-based online erasers are exact but require hand-masking each person. Describe-and-remove trades a little precision on edge cases for a large gain in speed on the ordinary case, which is the trade most marketing, real estate and event teams actually need.
Write the sentence before opening the tool. Upload the highest-resolution source available rather than a chat-compressed copy. Run one person at a time when the frame is crowded and several at once when the group is clearly separated. Download immediately, because the one-hour deletion window is real. Keep the original beside the result for the overlap cases, and hand those to a retoucher instead of retrying indefinitely.
If the queue is full of photos that cannot be retaken, with crowds, photo*removed*s or a passer-by in a listing shot, the describe-and-remove approach is the fastest first pass available. The tool and the sentence examples are at People Remover and the free first edit is enough to judge whether it fits the way your team works.
Grok Voice 3.0 turns text into speech and audio into editable text online. Choose a voice, create voiceovers, and download MP3 or WAV. Try it online today.
Most production teams do not have a voice problem. They have a routing problem. A script needs narration, so it goes to one service. An interview needs a transcript, so it goes to another. The outputs land in separate folders, the revisions live in separate tabs, and whoever owns the final cut spends the afternoon moving files between two systems that were never designed to talk to each other.
Grok Voice 3.0 is built around that gap. According to the product page, it places text to speech and speech to text inside a single browser workspace, so a project can move from script to voiceover, or from recording to editable transcript, without an export step in between. The workspace is at Grok Voice 3.0 and both modes are reachable from the same screen, which matters more than it sounds once a project starts bouncing in both directions.
Here is how the two halves fit together, and where a team still has to do the thinking.
1. Pick the direction before you pick a voice
The workspace opens on two modes: Text to Speech and Speech to Text. That split is the whole architecture. Text to Speech takes a script and returns audio. Speech to Text takes a recording and returns words. Everything else, including the asset library, is downstream of that first choice.
One detail worth noticing: the product page says you can draft as a guest and only sign in with Google or email when you are ready to generate. For a writer sketching a script, that removes a login wall from the part of the job that produces no billable output anyway.
2. What the text to speech side actually exposes
The script field accepts up to 60,000 characters per request. That is long enough for a full lesson or a chapter, but the product page recommends splitting longer material at topic changes and saving each section separately, which is also how most editors prefer to revise narration, because a single bad sentence does not force a full re-render.
Output formats go well past the usual two. The default is MP3 at 24 kHz, and the audio settings offer WAV, PCM, mu-law and A-law, with sample rates from 8 kHz to 48 kHz and MP3 bitrates from 32 to 192 kbps. Word-level timestamps can be switched on, which is the difference between guessing where a caption should start and knowing it.
The voice set is deliberately small: Eve, Ara, Atlas and Leo. The page describes Eve as a soothing female voice for lifestyle narration, Ara as an upbeat female voice for product ads, Atlas as a male storyteller for fiction and audio drama openers, and Leo as a crisp male voice for courses and explainers. Four voices with clear positioning is easier to brief than forty voices with none.
Language handling has one trap. You pick the language of the audio, but according to the product page, selecting a language does not translate the script. The text you paste has to already be in the language you want spoken. Teams that assume the selector translates will get a confidently wrong read.
3. What the transcription side exposes
On the other side, you upload an audio file up to 500 MiB or paste a public audio link, and the result arrives as a transcript you can review, copy, and download as a .txt file. Two toggles do most of the practical work: speaker labels for interviews, panels and two-host podcasts, and a clean-or-verbatim switch that either keeps filler words or drops them.
There is also a custom keyword list of up to 100 names, brands or technical terms. Anyone who has cleaned up a transcript full of mangled product names will recognise why that field exists.
4. The handoff is the reason to care
The feature that ties the two halves together is a button labelled Use as script. It moves a finished transcript straight into the text to speech editor. That single hop covers a workflow that otherwise takes three tools: record an interview, transcribe it, then turn the cleaned text into narration for a clip, a trailer or a second-language version.
Results from both directions are stored in My Creations, so a previous take is retrievable when a client asks for one more revision of the same paragraph.
5. Where a human still has to sit
Two things stay manual. First, review. A generated voiceover is a draft until someone listens to pronunciation, pacing and sentence endings, and a transcript is a draft until someone checks names and numbers against the recording. Second, cost control. The product page describes a credits model with an estimated credit count shown before a task when an estimate is available, which is useful only if the person running the task actually reads it before pressing generate.
6. A rollout checklist
Start with one real project rather than a demo script. Write the script in the language you want spoken, not in your working language. Split anything long at topic boundaries. Preview a short passage before rendering the full take, and turn on word timestamps if the audio will be paired with captions. For transcription, add brand and technical terms to the keyword list first, then decide clean versus verbatim per deliverable. Keep the .txt exports with the project files so the next revision does not start from the audio again.
Grok Voice 3.0 is not trying to be a full audio workstation. It is trying to remove the seam between speaking and writing, and for teams that produce both, that seam is where most of the lost hours actually live. If your work crosses that line more than once a week, the two-mode workspace at Grok Voice 3.0 is worth a direct look before you renew two separate subscriptions.
Turn ideas and images into cinematic clips with Kling 4.0 AI . Make videos up to 30s with synced sound, guided by references or keyframes. Start creating for free.
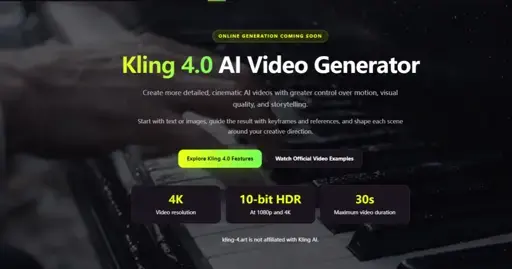
Kling 4.0 is the current generation of the Kling AI video model, and kling-4.art wraps it in a studio-style web interface: you start from a text prompt or an image, then shape the video with keyframes or reference media before generating and downloading the result. According to the product page, the site is an independent tool and is not affiliated with Kling AI itself.
Four capabilities the product page highlights:
1. Visual quality: up to 4K resolution, with 10-bit HDR available at 1080p and 4K. In the studio output settings, 720p and 1080p are selectable today and 4K is listed as coming soon. 2. Longer scenes: videos run from 3 to 30 seconds, giving actions and story beats room to develop. 3. Creative control: up to 10 keyframe images let you set visual checkpoints for movement, transitions, and scene progression. 4. Reference-driven creation: an Omni Reference mode guides the result with reference images, videos, audio, and subjects together. The upload panel accepts up to 10 reference images plus up to 5 reference videos (30 seconds total, shortest side at least 700 pixels).
How to create a video in three steps, as described on the product page:
Step 1. Choose how to start: a prompt, an image, first and last frames, keyframes, or reference files. Step 2. Describe your scene: subject, action, camera movement, and the details you want to stay consistent. Step 3. Generate and download: pick a duration between 3 and 30 seconds, an aspect ratio (16:9, 9:16, 1:1, or 21:9), then generate and download the result.
Credits are charged when a video is generated, at 5 credits per second; a 5-second clip is estimated at about 25 credits, and the estimate is shown before you generate.
The site also embeds a set of official Kling 4.0 example videos organized by creation method: text to video, image to video, first-frame input, last-frame input, multi-keyframe, Omni Reference, video editing (character and scene replacement), long-form generation, social media and UGC formats, game visualization, and flash-generation modes using image references or reference inputs. Watching a few of these is the fastest way to see which input style fits a given project.
For a typical content workflow, the reference pipeline matters most: keeping a product, a face, or a scene consistent across shots is the hard part of AI video, and the combination of up to 10 reference images with up to 5 reference videos is what the product page leans on for that. The keyframe path covers the opposite case, where you already know the specific moments you want to hit and let the model interpolate between them. The 3-30 second duration range also matters for pacing: it is long enough for a short ad or a story beat, which many shorter-clip generators do not cover.
A note on positioning: kling-4.art states clearly that it is not affiliated with Kling AI, so treat it as a third-party studio front-end for the model rather than an official channel. For anyone evaluating AI video tools, the variables worth testing here are keyframe control, reference consistency across scenes, and how the duration range handles story pacing.